Miles Whittaker · Platform engineer · UK

Platforms that
teams can own.

I build the automation, operating paths and self-service capabilities that help teams run reliable systems — shaped by enterprise-scale observability and incident-management work.

50+ teams supported3,000+ services in the estate800+ PagerDuty users
Miles Whittaker in a close-up indoor portrait
MW / 01
Miles WhittakerPlatform Engineer

About / 01

Reliability is a team
sport.

I’m Miles, a platform engineer at bet365 with a foundation in operations and infrastructure. Since moving into observability in 2024, I’ve led monitoring and incident-management transformation at enterprise scale — experience that now informs how I build platforms.

My work spans on-prem and GCP: replacing legacy monitoring, onboarding bespoke systems, and creating the automation and delivery paths that keep configuration consistent. I focus on more than tooling — clear ownership, practical training and self-service are what make platform change last.

I work across engineering teams and senior stakeholders to move response closer to the people who own each service: less central triage, less platform toil, and a clearer path from signal to action.
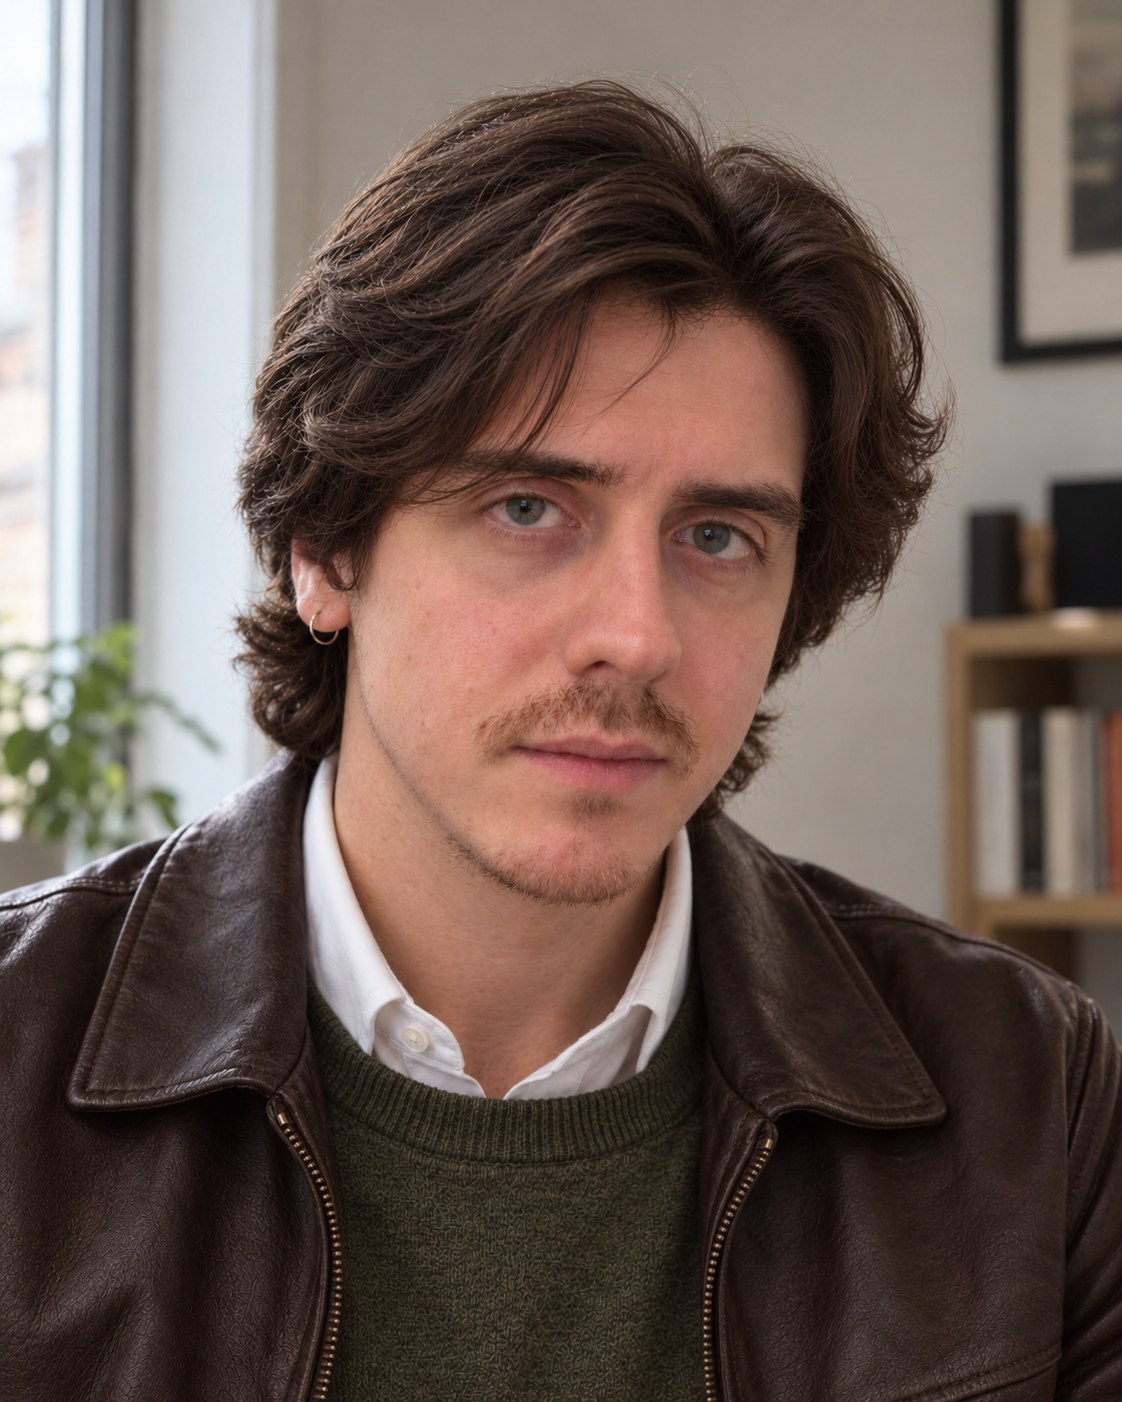
Selected platform work / 02

Change that lasts.

Platform outcomes, delivered through observability: modernising monitoring at scale, making delivery repeatable, and shifting incident response to service owners.

01 / Monitoring migrationOn-prem + GCP

From Nimsoft to New Relic

Migrated observability across tens of thousands of hosts and hundreds of microservices. Automated rollout with Ansible and built bespoke integrations in Bash, PowerShell and Flex/cURL for systems standard agents could not cover.

Terraform and GitLab brought monitoring configuration under version control, making it repeatable and team-owned.

  • New Relic
  • Ansible
  • Terraform
  • GitLab
  • Custom integrations
02 / Monitoring modernisationHundreds of checks

Off-host checks with Telegraf

Replaced legacy Nagios ICMP checks with a highly available Telegraf-based service supporting hundreds of checks. Standardised rollout with Ansible to reduce configuration drift and simplify onboarding.

Built a GitOps pipeline to lint, test with telegraf --test, and deploy using Terraform, Ansible and GCP Cloud Deploy.

  • Telegraf
  • Ansible
  • GitLab CI/CD
  • GCP Cloud Deploy
03 / Incident response50+ teams

PagerDuty to service ownership

Led adoption across 50+ teams, 800+ users and 3,000+ services. Developed Terraform modules and Events API integrations, with service provisioning automated from CMDB and GKE discovery.

Routed alerts directly to service owners, reducing reliance on central triage. Improved alert quality with standards, grouping, hygiene and auto-pausing.

  • PagerDuty
  • Terraform
  • Events API
  • CMDB + GKE discovery

Experience / 03

Experience &credentials.

Platform engineer building reliable, self-service foundations across hybrid environments. Combines enterprise-scale observability and incident-management transformation with hands-on infrastructure automation, cloud platforms and Kubernetes.

01 / PositioningCurrent focus

Platform engineering with an observability edge.

I build the automation, infrastructure-as-code and operating capabilities that help service teams ship, observe and own reliable systems across on-premises and cloud environments.

Platform engineeringInfrastructure as codeAutomationSelf-serviceObservabilityIncident management
02 / CredentialsSelected

Credentials that travel.

  • Certified Kubernetes Administrator (CKA)The Linux Foundation · August 2026 – August 2028
  • Google Cloud Associate Cloud EngineerGoogle Cloud · Valid through 2028
  • AWS Certified Solutions Architect – AssociateAmazon Web Services · Previously held; expired October 2025
View verified Credly profile ↗
03 / Application handoffRole fit

What I’m looking for next.

Primarily targeting Platform Engineering roles, with SRE and Forward Deployed Engineer roles also a strong fit where hands-on delivery, customer context and adoption matter.

Download CV (PDF)

Selected experience

Problem → intervention → result.

January 2024 – PresentObservability Engineer · bet365

Lead observability and incident-management transformation across on-premises and Google Cloud environments, supporting tens of thousands of hosts, more than 50 teams, 800+ PagerDuty users and 3,000+ services.

  • Led monitoring modernisation from Nimsoft to New Relic, automating rollout with Ansible and building custom Bash, PowerShell and Flex/cURL integrations for systems outside standard agent coverage.
  • Moved monitoring configuration into Terraform and GitLab CI/CD, making changes repeatable, reviewable and easier for service teams to own.
  • Standardised hundreds of off-host checks on Telegraf and built a highly available service with automated rollout and tested configuration.
  • Scaled PagerDuty service ownership with Terraform modules, Events API integrations and service discovery from CMDB and GKE; routed alerts closer to service owners and reduced reliance on central triage.
  • Implemented continuous profiling with Grafana Pyroscope on GCP/GKE and supported adoption through engineering training and stakeholder collaboration.
April 2023 – January 2024IT Operations Engineer · bet365

Owned monitoring, incident triage, service continuity and change operations for mission-critical systems.

Technical stack

Platform and containers · Kubernetes · GKE · Docker · Linux

Cloud and infrastructure as code · Google Cloud Platform · AWS · Terraform · Ansible

Observability and incident management · New Relic · PagerDuty · Telegraf · Grafana · Pyroscope

Delivery and automation · GitLab CI/CD · GitOps · Bash · PowerShell · REST APIs

Selected platform work

Evidence with clear boundaries.

GCP platform delivery and high-availability qualification

Designed a repeatable platform delivery path and qualified the shared workload in a hosted Kubernetes environment, including PostgreSQL high-availability and node-loss scenarios.

Hosted local qualification only. GCP provisioning, GKE, IAM, live zones and cloud costs remain unverified.

OPEN

Open to work

Platform engineering · hybrid or remote.

Based in the United Kingdom and open to Platform Engineering opportunities, alongside selected SRE and Forward Deployed Engineer roles. English is the authoritative site language for now.

Contact / 04

Have a system
worth making clearer?

For platform work, reliability engineering or a new opportunity, I’d like to hear what you’re building.

hello@alias.whitt.ukManchester · UK